class: center, middle, inverse, title-slide .title[ # Scalable methods for solving games in Adversarial Machine Learning ] .author[ ### Roi Naveiro ] .date[ ### EURO 2022 ] --- # Adversarial Machine Learning * Study and guarantee **robustness** of ML-based decisions wrt adversarial data manipulation. * Conflict adversary - learning system modeled as a **game**. * Classical Decision Makers, Humans: **discrete** and **low dimensional** decision spaces. * New Decision Makers, Algorithms: **continuous** and **high dimensional** decision spaces. <center> **Scalable gradient-based methods for solving sequential games in the new paradigm** --- # Motivation - Adversarial Regression * `\(R_J\)` and `\(R_D\)` are two competing wine brands. * `\(R_D\)` has a system to automatically measure wine quality training a regression over some quality indicators. (Response value: wine quality, Covariates: quality indicators). * `\(R_J\)`, aware of the actual superiority of its competitor's wines, decides to **hack** `\(R_D\)`'s system by manipulating the value of several quality indicators **at operation time**, to artificially decrease `\(R_D\)`'s quality rates. <center>  </center> --- # Motivation - Adversarial Regression * `\(R_D\)` is **aware** of the possibility of being hacked and decides to train its regression in an **adversarial robust** manner. * `\(R_D\)` models this **conflict** as a game between a *learner* `\((R_D)\)` and a *data generator* `\((R_J)\)`. (Brückner and Scheffer, 2011). * The *data generator* tries to fool the learner **modifying input data at application time**, inducing a change between the data distribution at training `\([p(x,y)]\)` and test `\([\bar{p}(x,y)]\)` times. --- # The Learner Problem * Given a feature vector `\(x \in \mathbb{R}^p\)` and target `\(y \in \mathbb{R}\)`, the learner's decision is to choose the weight vector of a linear model `\(f_w(x) = x^\top w\)`, minimizing **theoretical costs at application time** `\begin{eqnarray*} \theta_l (w, \bar{p}, c_l) = \int c_l(x,y) (f_w(x) - y)^2 \mathop{}\! \mathrm{d} \bar{p}(x,y), \end{eqnarray*}` * To do so, the learner has a training matrix `\(X \in \mathbb{R}^{n\times p}\)` and a vector of target values `\(y\in \mathbb{R}^n\)` (a sample from distribution `\(p(x,y)\)` at training time). --- # The Data Generator Problem * The data generator aims at **changing features of test instances** to induce a transformation from `\(p(x,y)\)` to `\(\bar{p}(x,y)\)`. * `\(z(x,y)\)` is the data generator's target value for instance `\(x\)` with real value `\(y\)` * The data generator aims at **choosing the data transformation** that minimizes the theoretical costs given by `\begin{eqnarray*} \theta_d (w, \bar{p}, c_d) = \int c_d(x,y) (f_w(x) - z(x,y))^2 \mathop{}\! \mathrm{d} \bar{p}(x,y) + \Omega_d(p,\bar{p}) \end{eqnarray*}` --- # Regularized Empirical Costs * Theoretical costs defined above depend on the unknown distributions `\(p\)` and `\(\bar{p}\)`. * We focus on their regularized empirical counterparts, given by `\begin{eqnarray*} \widehat{\theta}_l(w, \bar{X}, c_l) &=& \sum_{i=1}^n c_{l,i} (f_w(\bar{x}_i) - y_i)^2 + \Omega_l(f_w),\\ \widehat{\theta}_d(w, \bar{X}, c_d) &=& \sum_{i=1}^n c_{d,i} (f_w(\bar{x}_i) - z_i)^2 + \Omega_d(X, \bar{X}). \end{eqnarray*}` --- # Resulting Stackelberg Game * We assume the learner acts first, choosing a weight vector `\(w\)`. Then the data generator, after observing `\(w\)`, chooses his optimal data transformation. <br/> <br/> <center>  </center> --- # The general problem Defender (D) makes decision `\(\alpha \in \mathbb{R}^n\)`. Attacker (A), after observing `\(\alpha\)`, makes decision `\(\beta \in \mathbb{R}^m\)` <br/> <br/> <center>  </center> -- * In AML, `\(\alpha\)` and `\(\beta\)` usually **high dimensional** and **continuous**. --- # Gradient Methods * Forget about analytical solutions! * **Gradient methods** require computing `\(\mathop{}\! \mathrm{d}_\alpha u_D\)` (and moving `\(\alpha\)` in the direction of increasing gradient...) <br/> <center>  </center> * Inverting the Hessian has cubic complexity! * We need a different strategy... --- # Backward Solution * Under **certain conditions** (Bottou, 1998), we can approximate our problem by <br/> <br/> <center>  </center> * Where `\(T \gg 1\)`. * `\(\lim_{t \rightarrow \infty} \beta(\alpha, t) = \beta^*(\alpha)\)`. * Let's try to solve this problem instead. --- # Backward Solution * It can be proved that (Naveiro and Ríos, 2019) <br/> <center>  </center> * Provided that `\(\lambda\)` satisfies the **adjoint equation** <br/> <center>  </center> * With initial conditions `\(\lambda(T) = - \partial_\beta u_D(\alpha, \beta)\)`. --- # Backward Solution <center>  </center> --- # Backward Solution - Complexity Analysis ## Time complexity * If `\(\tau (n,m)\)` is the time required to evaluate `\(u_D(\alpha, \beta)\)` and `\(u_A(\alpha, \beta)\)`, computing their derivatives requires time `\(\mathcal{O}(\tau (n,m))\)`. * First loop `\(\mathcal{O}(T \tau (n,m))\)`. * Second loop needs computing Hessian Vector Products, by basic results of AD, they have same complexity as function evaluations! * Thus, overall time complexity is `\(\mathcal{O}(T\tau (n,m))\)`. -- ## Space complexity * We need to store `\(\beta_t(\alpha)\)` for all `\(t\)`. * `\(\sigma(n,m)\)` is the space requirement for storing each `\(\beta_t(\alpha)\)`. * Overall space complexity `\(\mathcal{O}(T \sigma(n,m))\)`. --- # Forward Solution * Under **certain conditions**, we can approximate our problem by <br/> <br/> <center> 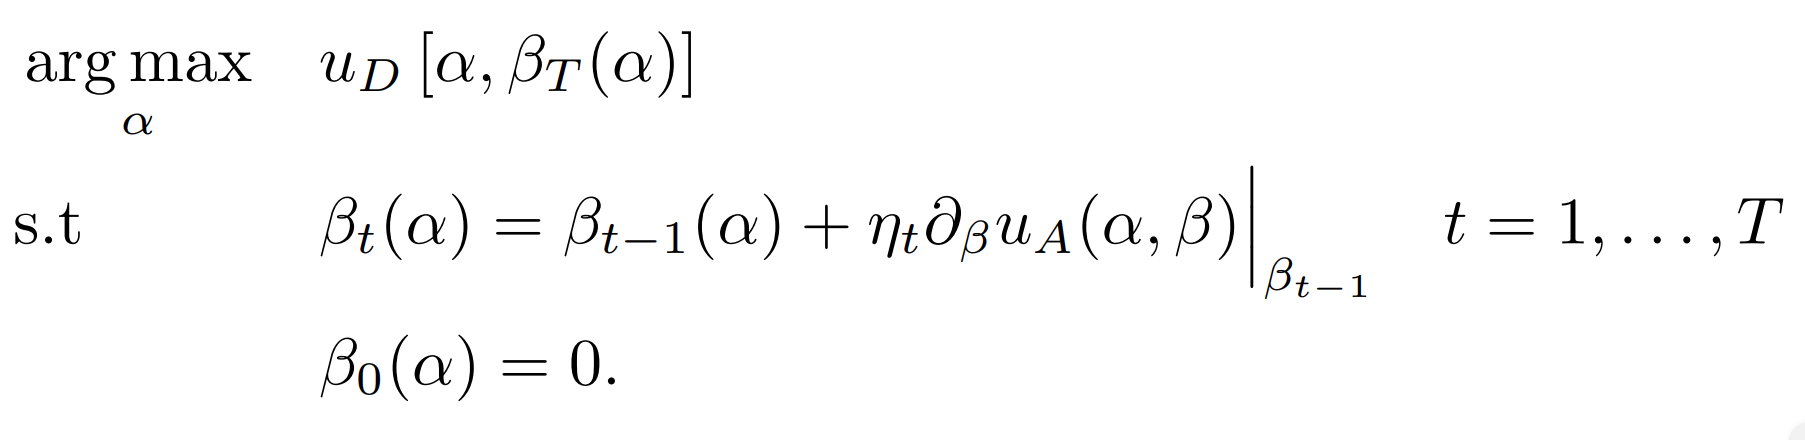 </center> * Again, `\(T \gg 1\)`. * `\(\lim_{t \rightarrow \infty} \beta_t(\alpha) = \beta^*(\alpha)\)`. --- # Forward Solution * Using the chain rule <br/> <center> 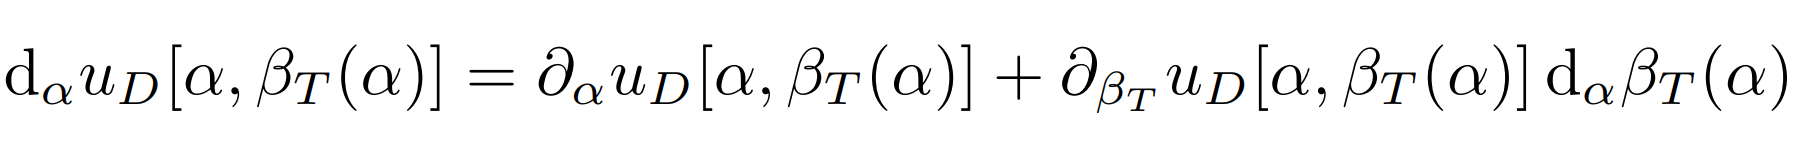 </center> * To obtain `\(\mathop{}\! \mathrm{d}_\alpha \beta_T(\alpha)\)` we can sequentially compute <center> 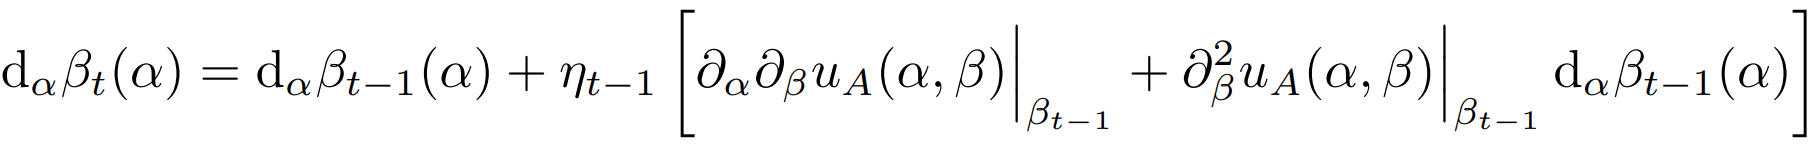 </center> * This induces a dynamical system in `\(\mathop{}\! \mathrm{d}_\alpha \beta_t(\alpha)\)` that can be iterated in parallel to the dynamical system in `\(\beta_t(\alpha)\)`! --- # Forward Solution <br/> <br/> <center> 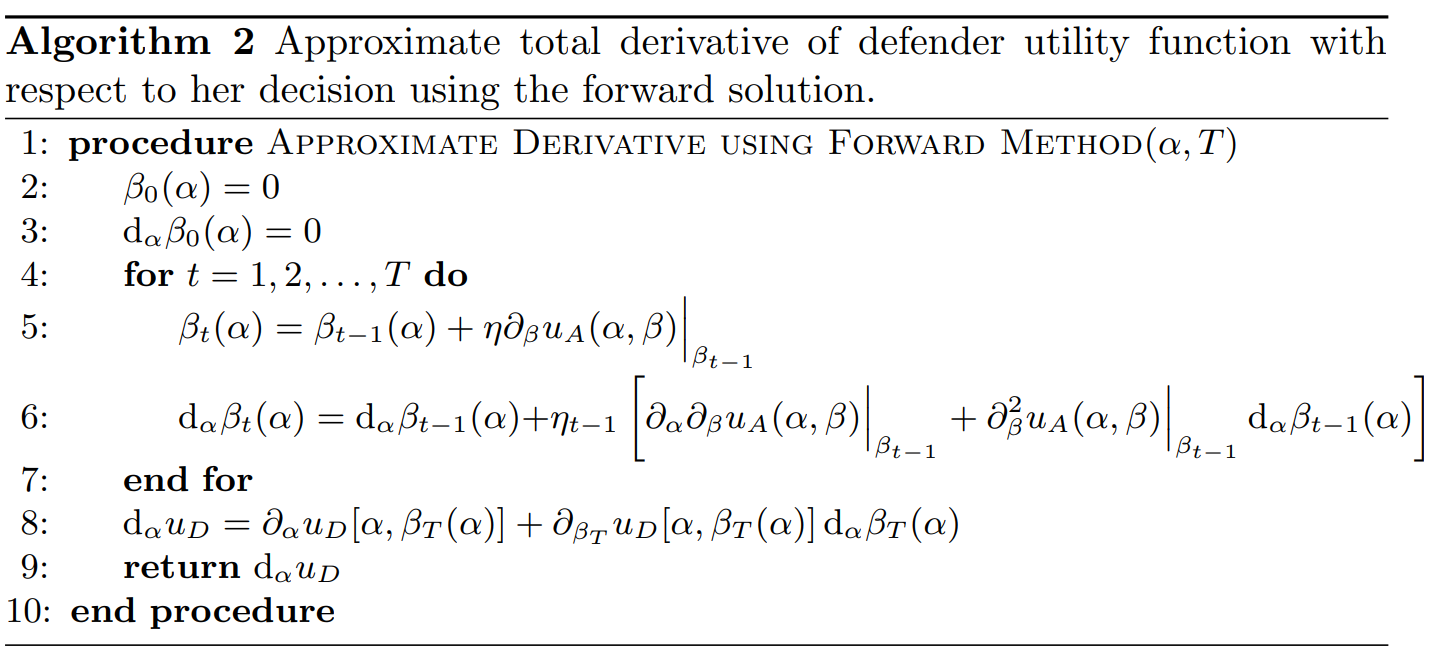 </center> --- # Forward Solution - Complexity Analysis ## Time complexity * Computing `\(\partial^2_\beta u_A(\alpha, \beta)\)` requires time `\(\mathcal{O}(m \tau(m,n))\)` as it requires computing `\(m\)` Hessian vector products. * Computing `\(\partial_\alpha \partial_{\beta} u_A(\alpha, \beta)\)` requires computing `\(n\)` Hessian vector products and thus time `\(\mathcal{O}(n \tau(m,n))\)`. * If we compute the derivative in the other way, first we derive with respect to `\(\beta\)` and then with respect to `\(\alpha\)`, the time complexity is `\(\mathcal{O}(m \tau(m,n))\)`. * Thus, computing `\(\partial_\alpha \partial_{\beta} u_A(\alpha, \beta)\)` requires `\(\mathcal{O}(\min(n,m) \tau(m,n))\)`. * Overall, `\(\mathcal{O}(\max[\min(n,m), m]T\tau(m,n))=\mathcal{O}(mT \tau(m,n))\)`. -- ## Space complexity * The values `\(\beta_t(\alpha)\)` are overwritten at each iteration. * Overall space complexity is `\(\mathcal{O}( \sigma(m,n))\)`. --- # Conceptual Example * Attacker's utility is `\(u_A(\alpha, \beta) = -\sum_{i=1}^n 3(\beta_i - \alpha_i)^2\)` and the defender's one is `\(u_D(\alpha, \beta) = -\sum_{i=1}^n (7 \alpha_i + \beta_i^2)\)`. * `\(\mathcal{O}(T \tau(m,n))\)` vs `\(\mathcal{O}(mT \tau(m,n))\)`. <center>  </center> --- # Application - Adversarial Regression * We compare ridge regression versus *adversarial robust regression* in the wine problem. * For ridge regression, we compute the weights in the usual way, and test them in data attacked using those weights. * For *adversarial robust regression* we compute the weights solving <center>  </center> and test them in data attacked using those weights. * Note the dimension of the attacker's decision space is huge! He needs to modify `\(k=3263\)` data points each with `\(n=11\)` components! --- # Adversarial Regression <br/> <center>  </center> --- # Conclusions and future work * New algorithmic method able to solve **huge Stackelberg Games** (dimension of decision sets of the order of `\(10^4\)`). * Could be implemented in any **Automatic Differentiation** library (Pytorch, tensorflow...). * Novel derivation of the backward solution formulating the Stackelberg game as a PDE-constrained optimization problem. -- * Application to games with uncertain outcomes. * Application to Bayesian Stackelberg Games and ARA. * Several attackers? --- class: middle, center, inverse # Thank you!! <span style="color:cyan">roi.naveiro@icmat.es</span> <span style="color:cyan">www.github.com/roinaveiro/GM_SG</span> <span style="color:cyan">www.roinaveiro.github.io</span>