Simulation-based Bayesian Optimization
CUNEF University
Motivation - ML for Molecular Design
ML for Molecular Design
Pharma: average time discovery - market, 13 years (outside pharma: 25 years)
Crucial 1st step: generate pool of candidates
Daunting task (e.g. \(10^{23}\) – \(10^{60}\) drug-like molecules)
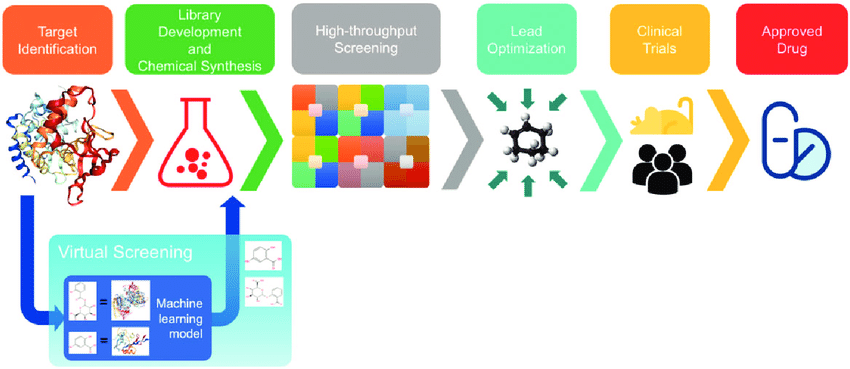
De novo molecular design
Traditionally: human experts propose, synthesize and test molecules (in vitro)
Generate novel molecules with optimal properties by leveraging ML activity-structure relationship models
Motivation
This usually requires solving optimizations that are
Combinatorial
Black-box
Stochastic
Multi-objective
The problem
Find extreme of objective function
\[\begin{equation*} \arg\max_{x \in \mathcal{S}} f(x) \end{equation*}\]
Possibly discrete structured domain \(\mathcal{S}\) (e.g. \(\mathcal{S} = [k]^p\))
No closed form for \(f(x)\)
\(f(x)\) is expensive to evaluate
We can query at \(x\) and obtain a (possibly noisy) evaluation of \(f(x)\)
Goal
Get good estimates of global maximum, with few objective function evaluations
A possible way to go: Bayesian Optmization
Bayesian Optimization (in a nutshell)
Imagine we have access to: \(\mathcal{D}_{1:T} = \lbrace x_t, y_t \rbrace_{t=1}^T\) where
\[y_t \equiv y(x_t) \equiv f(x_t) + \epsilon, ~~~~~ \epsilon \sim \mathcal{N}(0, \sigma^2)\]
Problem: Using this information, decide where to evaluate next: \(x_{t+1}\)
Solution: Location with max Expected Utility1
Bayesian Optimization (in a nutshell)
To do this:
Create probabilistic (Bayesian) model of response \(y\) given covariates \(x\)
Given prior knowledge about \(f(x)\) and evidence coming from \(\mathcal{D}_{1:T}\), summarise our beliefs about result if we query at \(\bf{x_{T+1}}\) through the Posterior Predictive Distribution
\[\begin{equation*} \pi[y_{T+1} | x_{T+1}, \mathcal{D}_{1:T}] \end{equation*}\]
Bayesian Optimization (in a nutshell)
- Find
\[\begin{eqnarray*} x^*_{T+1} &=& \arg\max_{x_{T+1} \in \mathcal{S}} \mathbb{E}_{y_{T+1} | x_{T+1}, \mathcal{D}_{1:T}} [u(y_{T+1}, x_{T+1} )] \\ &=&\arg\max_{x_{T+1} \in \mathcal{S}} \int u(y_{T+1}, x_{T+1} ) \pi(y_{T+1} | x_{T+1}, \mathcal{D}_{1:T}) d y_{T+1} \end{eqnarray*}\]
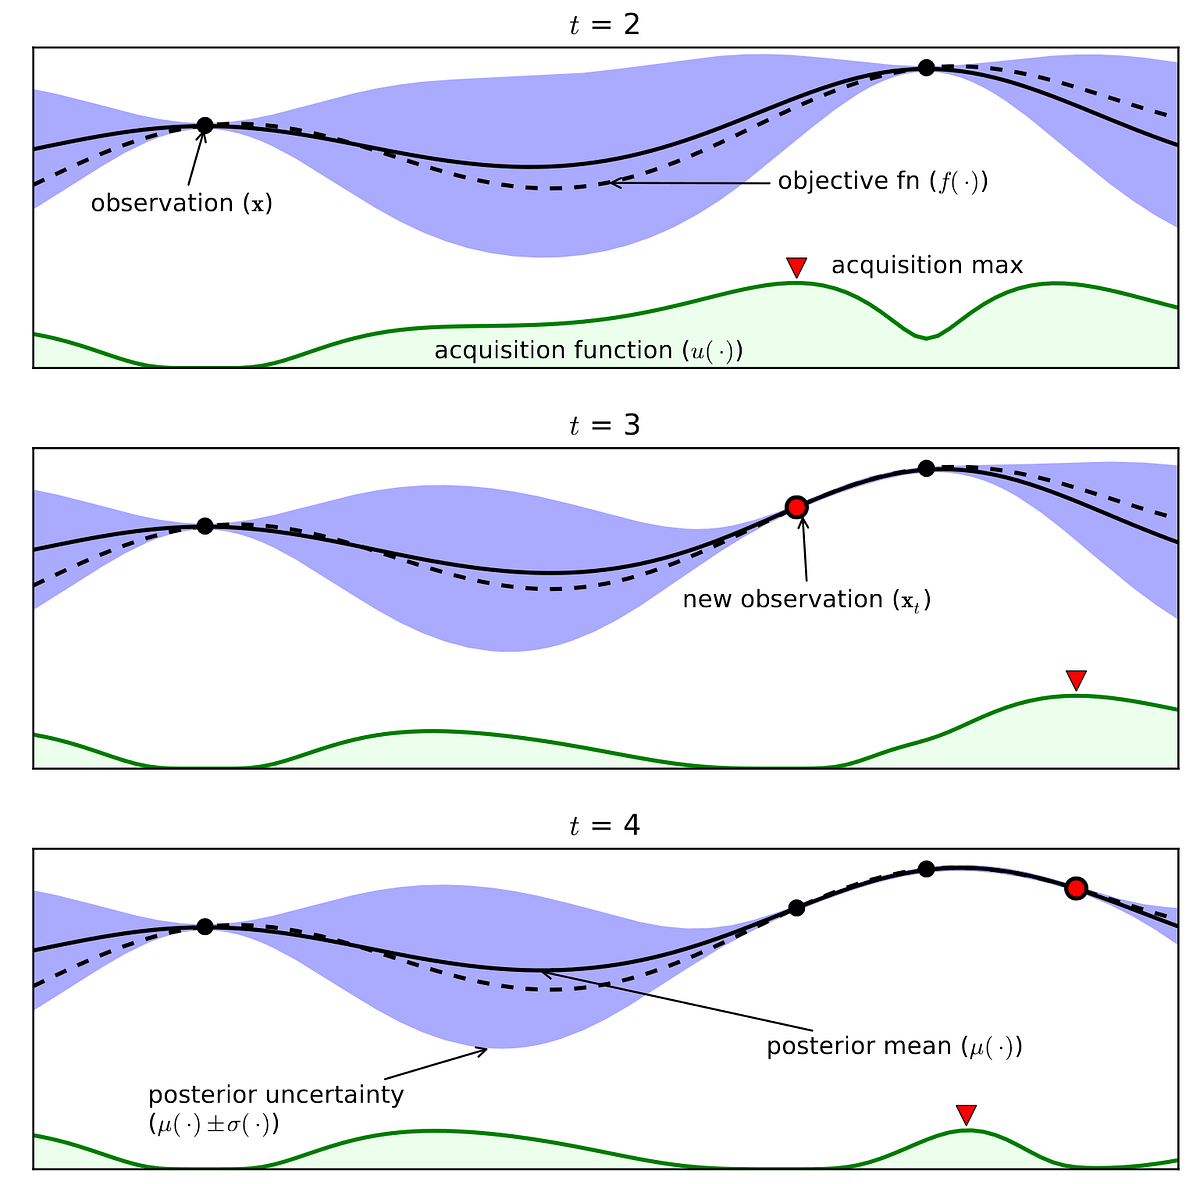
Exploration - Exploitation
Utility function balances exploration and exploitation
Common one: Expected Improvement
\[\begin{equation*} u(y_{T+1}) = \max(y_{T+1} - y^*, 0) \end{equation*}\]
Exploration - Exploitation
Bayesian Optimization - Difficulties
\(\mathcal{S}\) could be a combinatorial search space (or even more complex!). We need:
Suitable models of response given covariates
Solve a combinatorial optimization in Step 3.
SBBO
We propose Simulation Based Bayesian Optimization (SBBO): an approach to 2 that just requires sampling from posterior predictive distribution
\[\begin{equation*} \pi[y_{T+1} | x_{T+1}, \mathcal{D}_{1:T}] \end{equation*}\]
allowing us to use a wide variaty of models which are suitable for combinatorial spaces
SBBO - Main idea
Convert EU maximization into a simulation problem.
The EU is:
\[\begin{eqnarray*} \Psi(x) \equiv \int u(y, x ) \cdot \pi(y \vert x, \mathcal{D}_{1:T} ) d y \end{eqnarray*}\]
Given non-negative and bounded utility, recast EU maximization as a simulation from
\[\begin{eqnarray*} g(x, y) \propto u(y, x ) \cdot \pi(y \vert x, \mathcal{D}_{1:T} ) \end{eqnarray*}\]
NOTE: mode of marginal in \(x\) is \(x^*_{T+1}\)!
SBBO - Main idea
- We could simulate from \(x,y \sim g(y, x)\) and find the mode in \(x\)… just limited for low dimensional \(x\)
SBBO - Main idea
- Alternative, Muller et. al. (2004): auxiliary distribution
\[\begin{eqnarray*} g_H(x, y_1, \dots, y_H) \propto \prod_{h=1}^H u(y^h, x ) \cdot \pi(y^h \vert x, \mathcal{D}_{1:T} ) \end{eqnarray*}\]
for positive integer \(H\). Marginal in \(x\)
\[\begin{eqnarray*} g_H(x) \propto \Psi(x)^H \end{eqnarray*}\]
SBBO - Main idea
Inhomogeneus MCMC simulation from \(g_H(y, x)\) with increasing \(H=H_n\) such that stationary distribution for fixed \(H\) is \(g_H\), converges to \(x^*_{T+1}\)!
Use Metropolis scheme for fixed \(H\)
Gradually increase \(H\)
SBBO - Metropolis
Recall \(x \in [k]^p\) is a \(p\)-dimensional vector of \(k\)-levels categorical variables.
Metropolis sampling scheme for fixed \(H\) with:
A symmetric proposal for each dimension \(x_q\)
\(\pi(y^h \vert x, \mathcal{D}_{1:T})\) as proposal for \(y_h\)
SBBO - Metropolis
Assume current state of chain is \(x, y_1, \dots, y_H\).
Define \(v = \frac{1}{H} \sum_h \log u(x, y_h)\). Iterate:
For \(q=1, \dots, p\):
Sample \(\tilde{x}_q\) from symmetric proposal
Sample \(\tilde{y}_h \sim \pi(y^h \vert \tilde{x}_q \cup x_{-q}, \mathcal{D}_{1:T} )\) for \(h=1, \dots, H\)
Evaluate \(\tilde{v} = \frac{1}{H} \sum_h \log u(\tilde{x}_q \cup x_{-q}, \tilde{y}_h)\)
With probability \(\min \left[1, \exp (H \tilde{v} - H v)\right]\) set \(v = \tilde{v}\) and \(x = \tilde{x}_q \cup x_{-q}\)
Increase \(H\) according to chosen schedule
SBBO - Implementation details
We run the previous algorithm increasing \(H\) until certain value.
Last generated \(x\) is the new evaluation
We propose several probabilistic models of response given discrete covariates for which we have sampling access to their posterior predictive distribution (PPD)
SBBO - Tanimoto GP
Uncertainty on \(f(x)\) modelled through Gaussian Process
\(x \in \lbrace 0, 1 \rbrace^p\). Kernel function:
\[\begin{equation*} k(x, x') = \frac{x \cdot x'}{\Vert x \Vert^2 + \Vert x' \Vert^2 - x \cdot x'} \end{equation*}\]
- PPD is Gaussian with certain mean and variance analytically available
SBBO - Sparse Bayesian linear regression
As in Baptista and Poloczek (2018): \[\begin{eqnarray*} && y = \alpha_0 + \sum_j \alpha_j x_j + \sum_{i,j>i} \alpha_{ij} x_i x_j + \epsilon\\ % && \alpha_k \vert \beta_k, \tau, \sigma^2 \sim \mathcal{N}(0, \beta_k^2 \tau^2 \sigma^2)\\ % && \beta_k, \tau \sim \mathcal{C}^+(0, 1)\\ % && P(\sigma^2) \propto \sigma^{-2} \end{eqnarray*}\]
- PPD accesible through MCMC (Gibbs sampler)
SBBO - NGBoost
Duan et. al. (2020):
Output given covariates modelled through \(y \vert x \sim P_\theta (x)\)
Where \(\theta(x)\) are obtained through an additive combination of \(M\) base learners and an initial \(\theta^{(0)}\)
\[ \theta = \theta^{(0)} - \eta \sum_{m=1}^M \rho^{(m)}\cdot f^{(m)} (x) \]
- Learners are trained to minimize a proper scoring rule using a refinement of gradient boosting
SBBO - NGBoost
Any base learner can be used
Base learners used: shallow decision trees and linear regressions with lasso regularization
PPD directly accesible
Experimental Results
Two Benchmarks
Initial dataset \(\mathcal{D}_{1:T} = \lbrace x_t, y_t \rbrace_{t=1}^T\) with \(T=5\)
For \(t=500\) iterations:
- Use SBBO to propose next sample: \(x_{t+1}\)
- Evaluate true objective: \(y_{t+1}(x_{t+1})\)
- Update dataset wiht \((x_{t_1}, y_{t+1})\)
Report best function value after \(t\) evaluations of true objective, averaged over 10 runs (plus/minus one standard error).
Experimental Results
- Learners:
- Sparse Bayesian linear regression (BOCS)
- NGBoost: decision tree (NGBdec), lasso (NGBlinCV)
- GP with Tanimoto (GPr)
- Simulated Annealing (SA)
- Random Local Search (RS)
Binary Quadratic Problem
- We want to maximize
\[\begin{equation*} x^T Q x - \lambda \Vert x \Vert_1 \end{equation*}\]
over \(\lbrace 0,1 \rbrace^d\), with \(d=10\).
Result
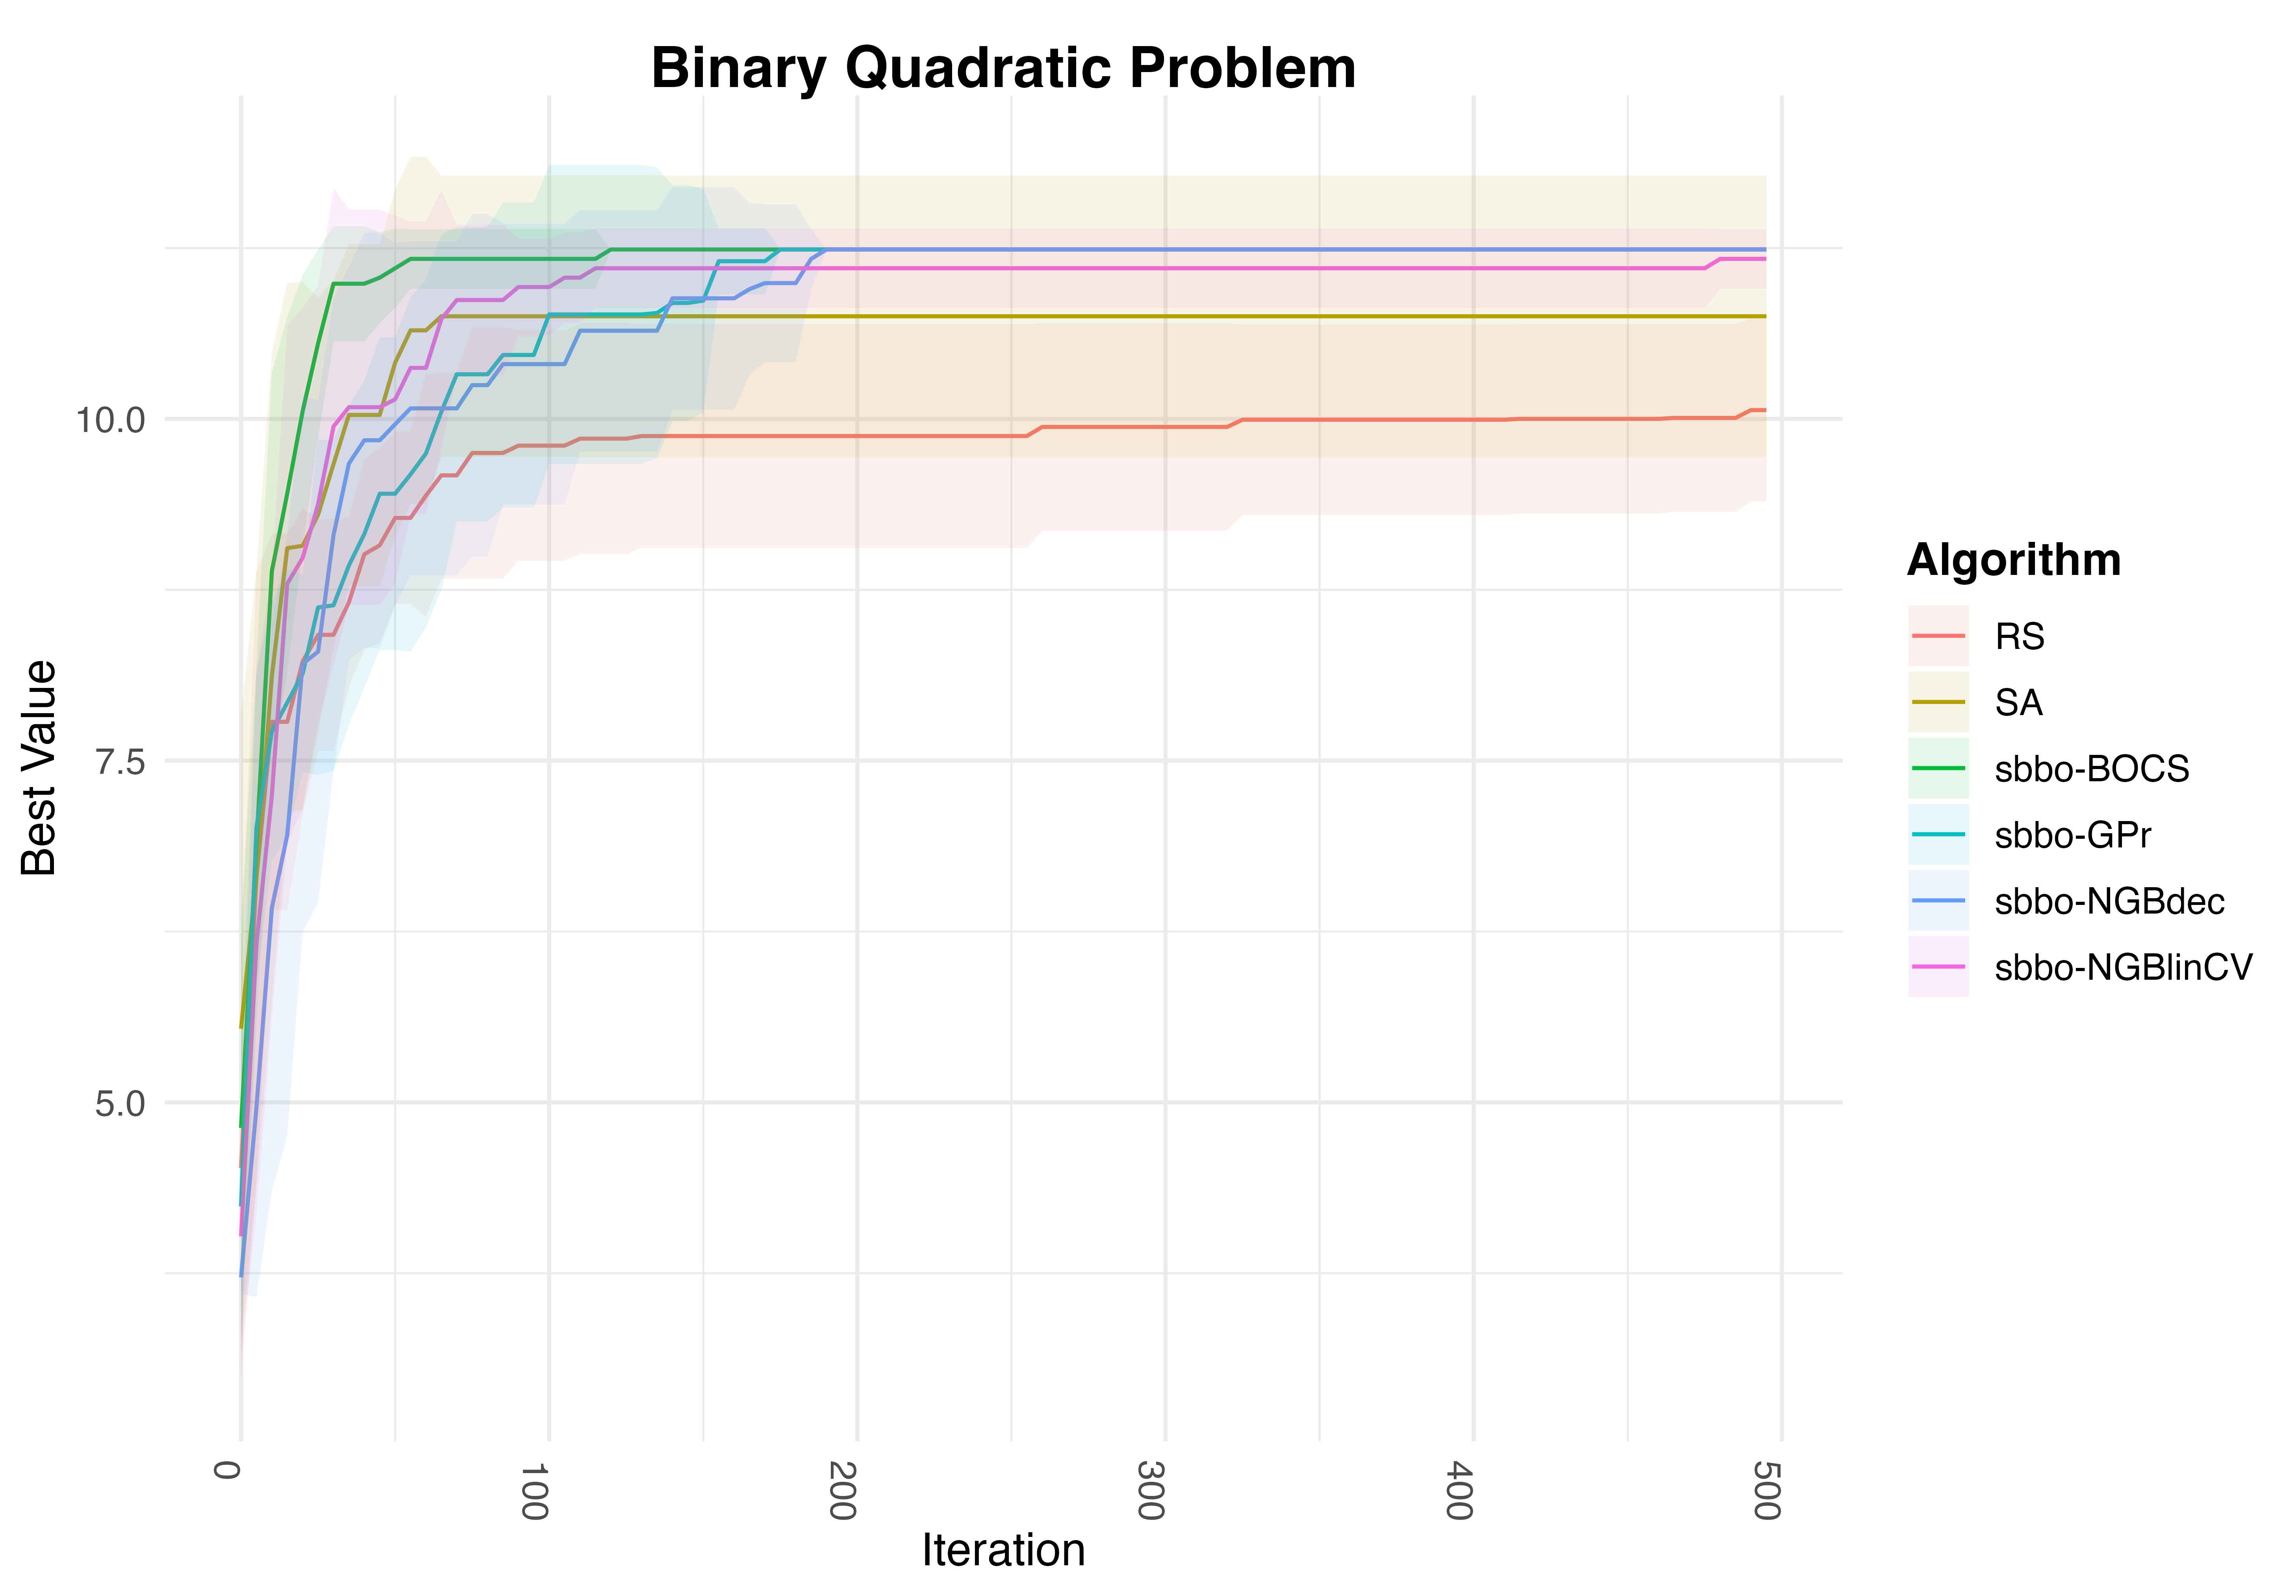
Number of Function Evaluations vs Best Value found for BQP
Contamination Problem
Food supply with \(d=25\) stages that maybe contaminated
\(Z_i\) denotes fraction of food contaminated at \(i\)-th stage
At stage \(i\), prevention effort (with cost \(c_i\)) can be made \((x_i = 1)\) decreasing contamination a random rate \(\Gamma_i\)
If no prevention is taken \((x_i = 0)\), contamination spreads with random rate \(\Lambda_i\)
\[\begin{equation*} Z_i = \Lambda_i (1-x_i)(1 - Z_{i-1}) + (1 - \Gamma_i x_i) Z_{i-1} \end{equation*}\]
Contamination Problem - Goal
Decide for each stage whether to intervene or not to minimize cost (\(2^d = 2^{25}\))
Ensuring fraction of cont. food does not exceed \(U_i\) with probability at least \(1-\epsilon\)
Lagrangian relaxation
\[\begin{equation*} \arg\min_x \sum_{i=1}^d \left[ c_i x_i + \frac{\rho}{T} \sum_{k=1}^T \left(1_{\lbrace Z_{ik} > U_i \rbrace} - (1- \epsilon)\right)\right] + \lambda \Vert x \Vert_1 \end{equation*}\]
Results
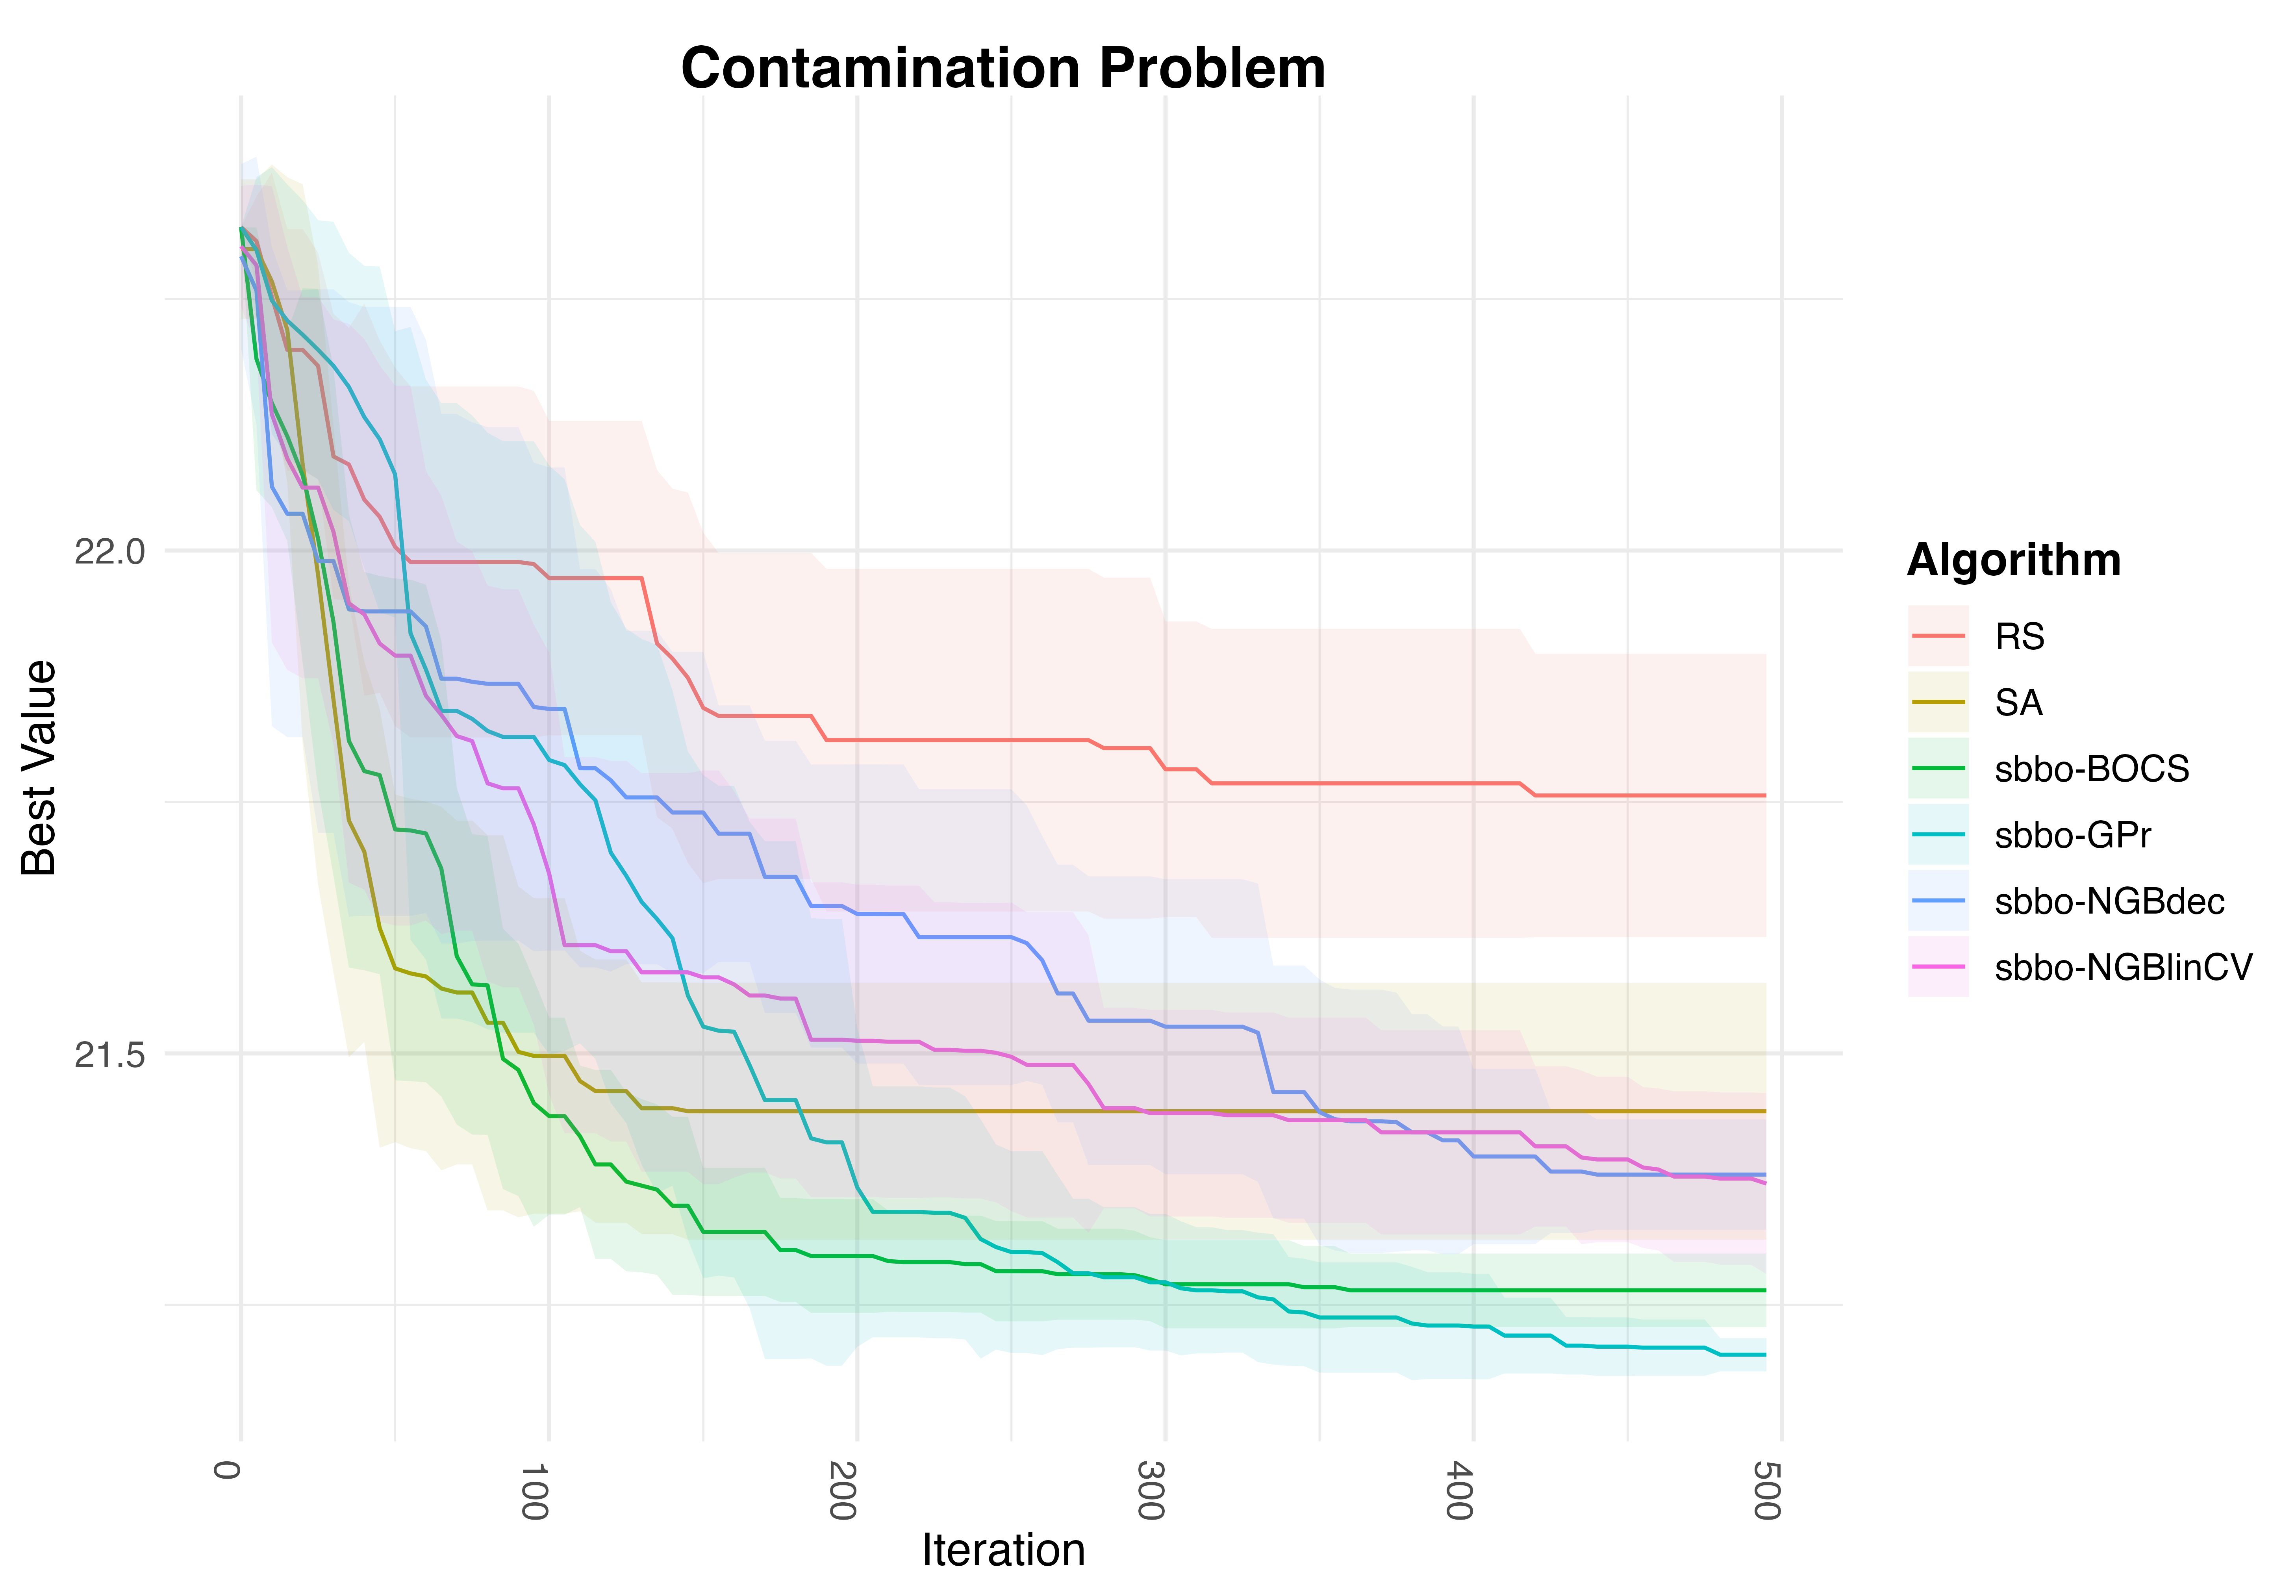
Number of Function Evaluations vs Best Value found for CP
Results - Why?
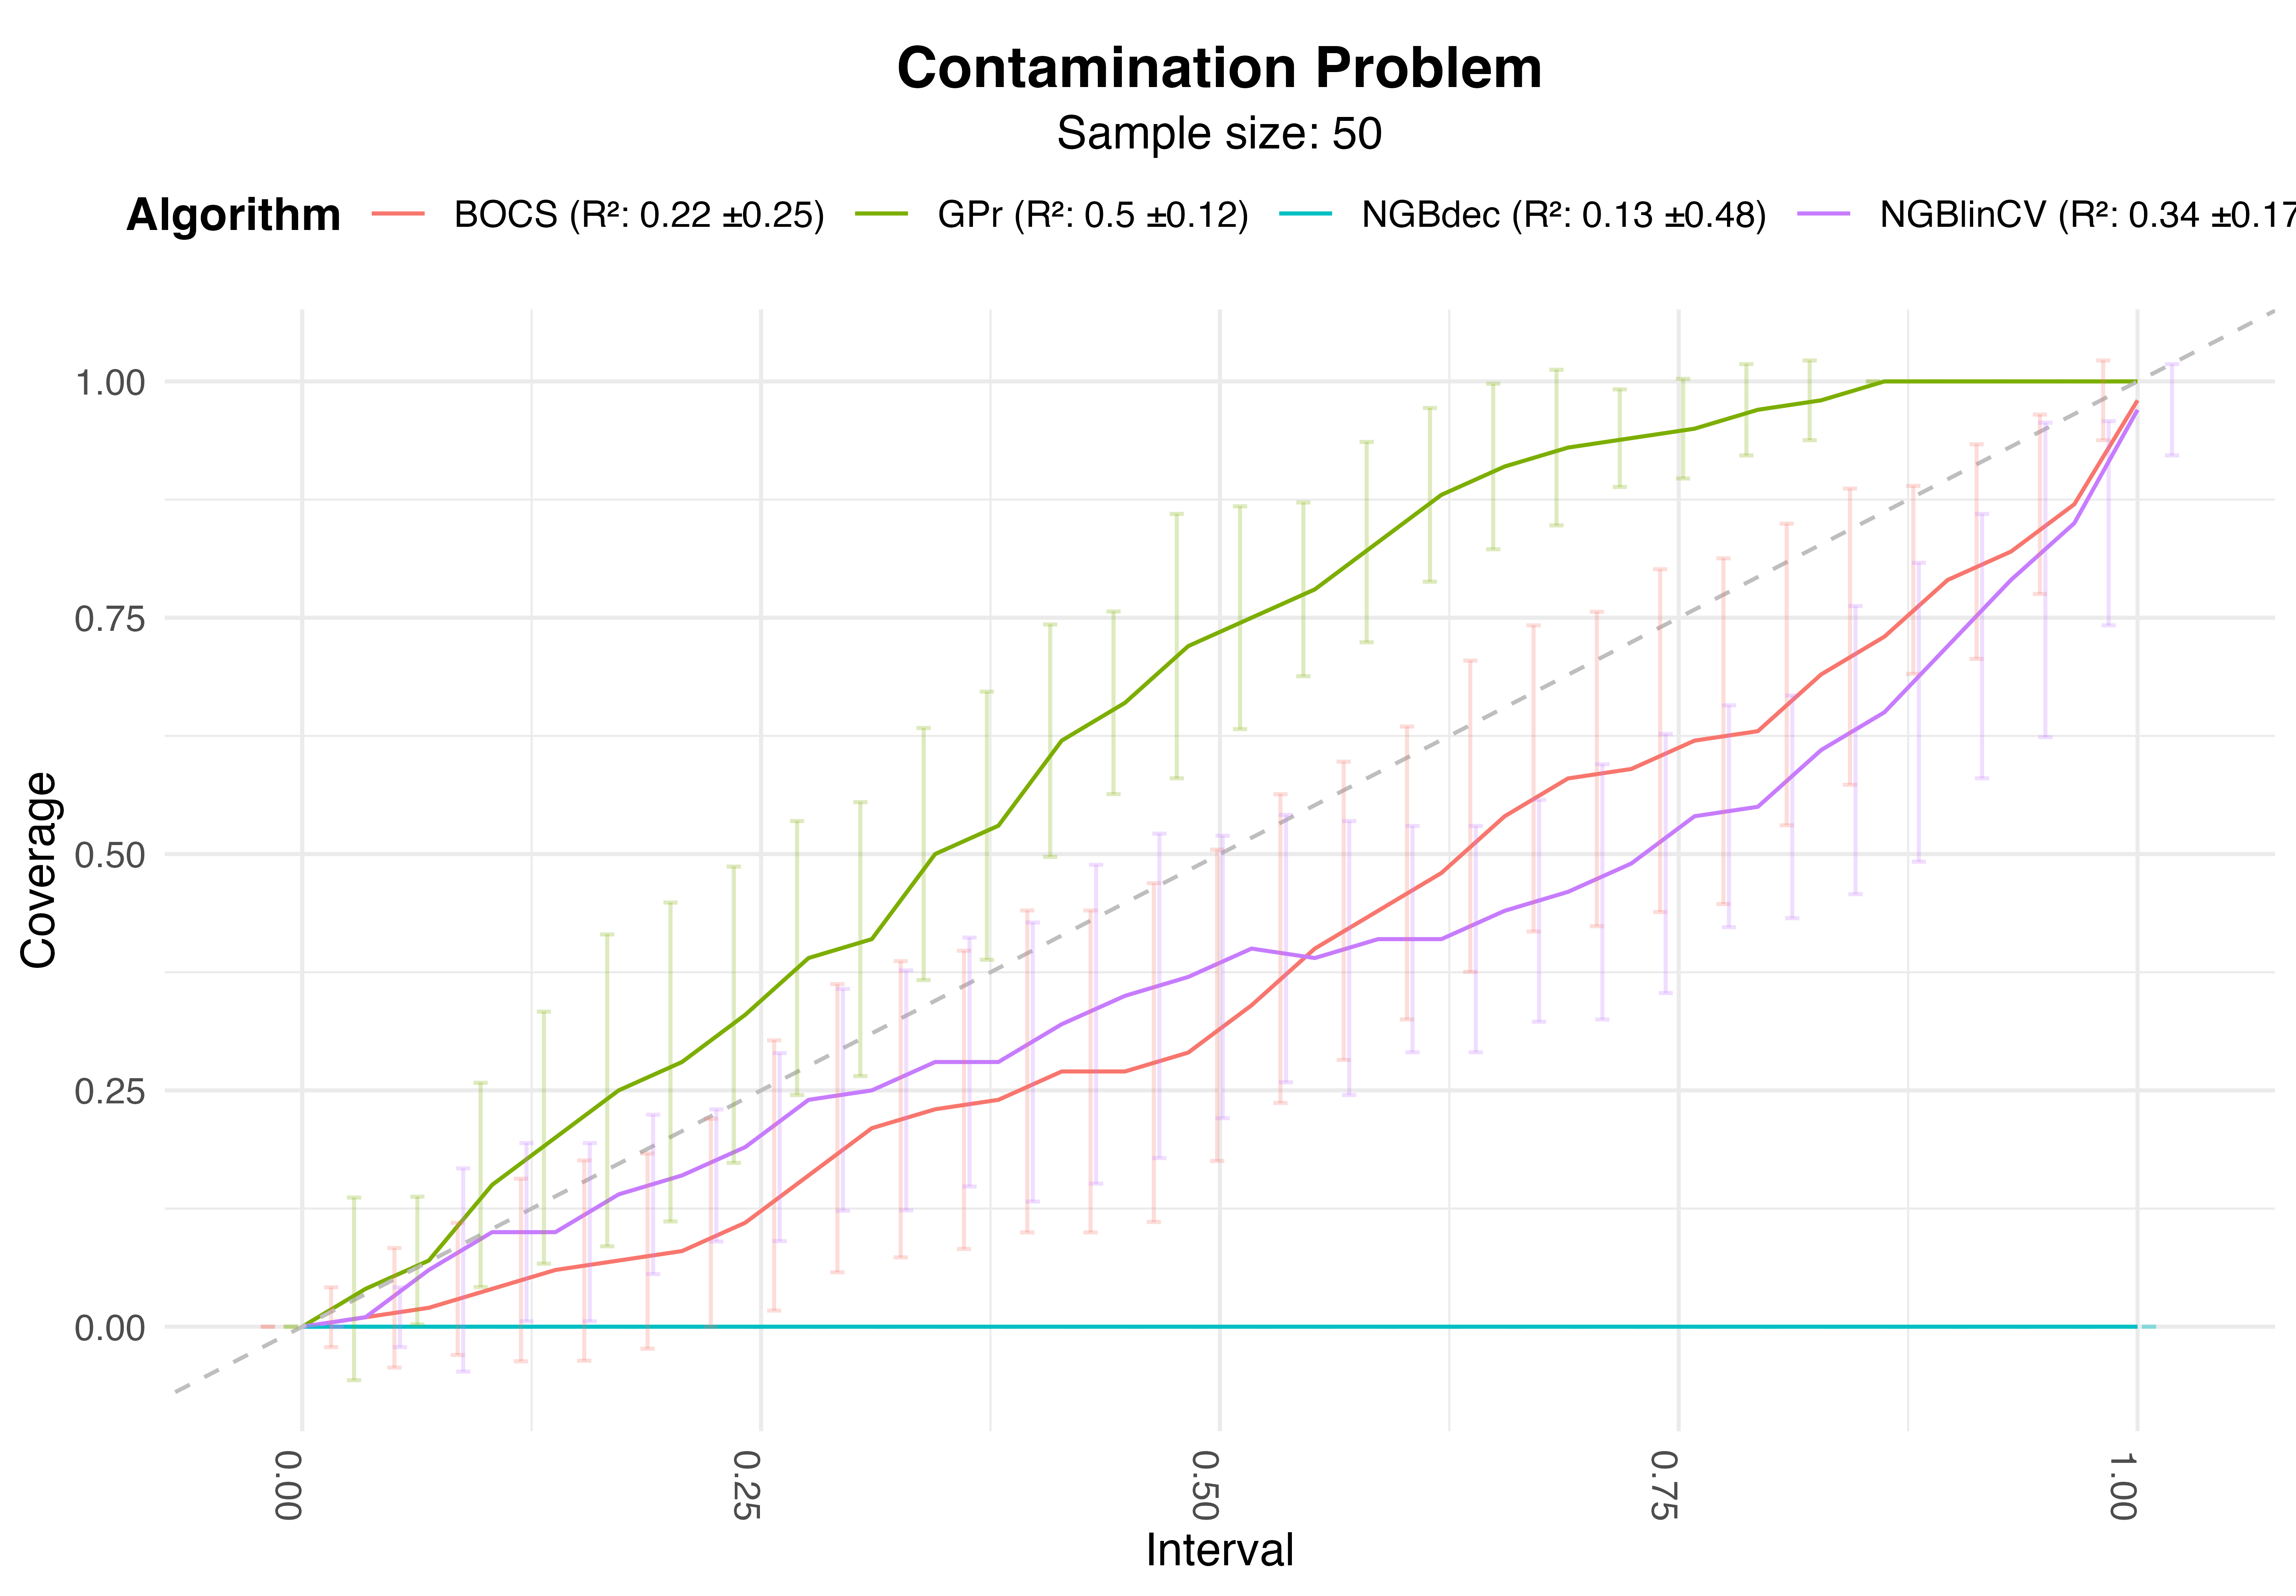
Calibrartion Plot and Performance Metrics. Sample size: 50
Results - Why?
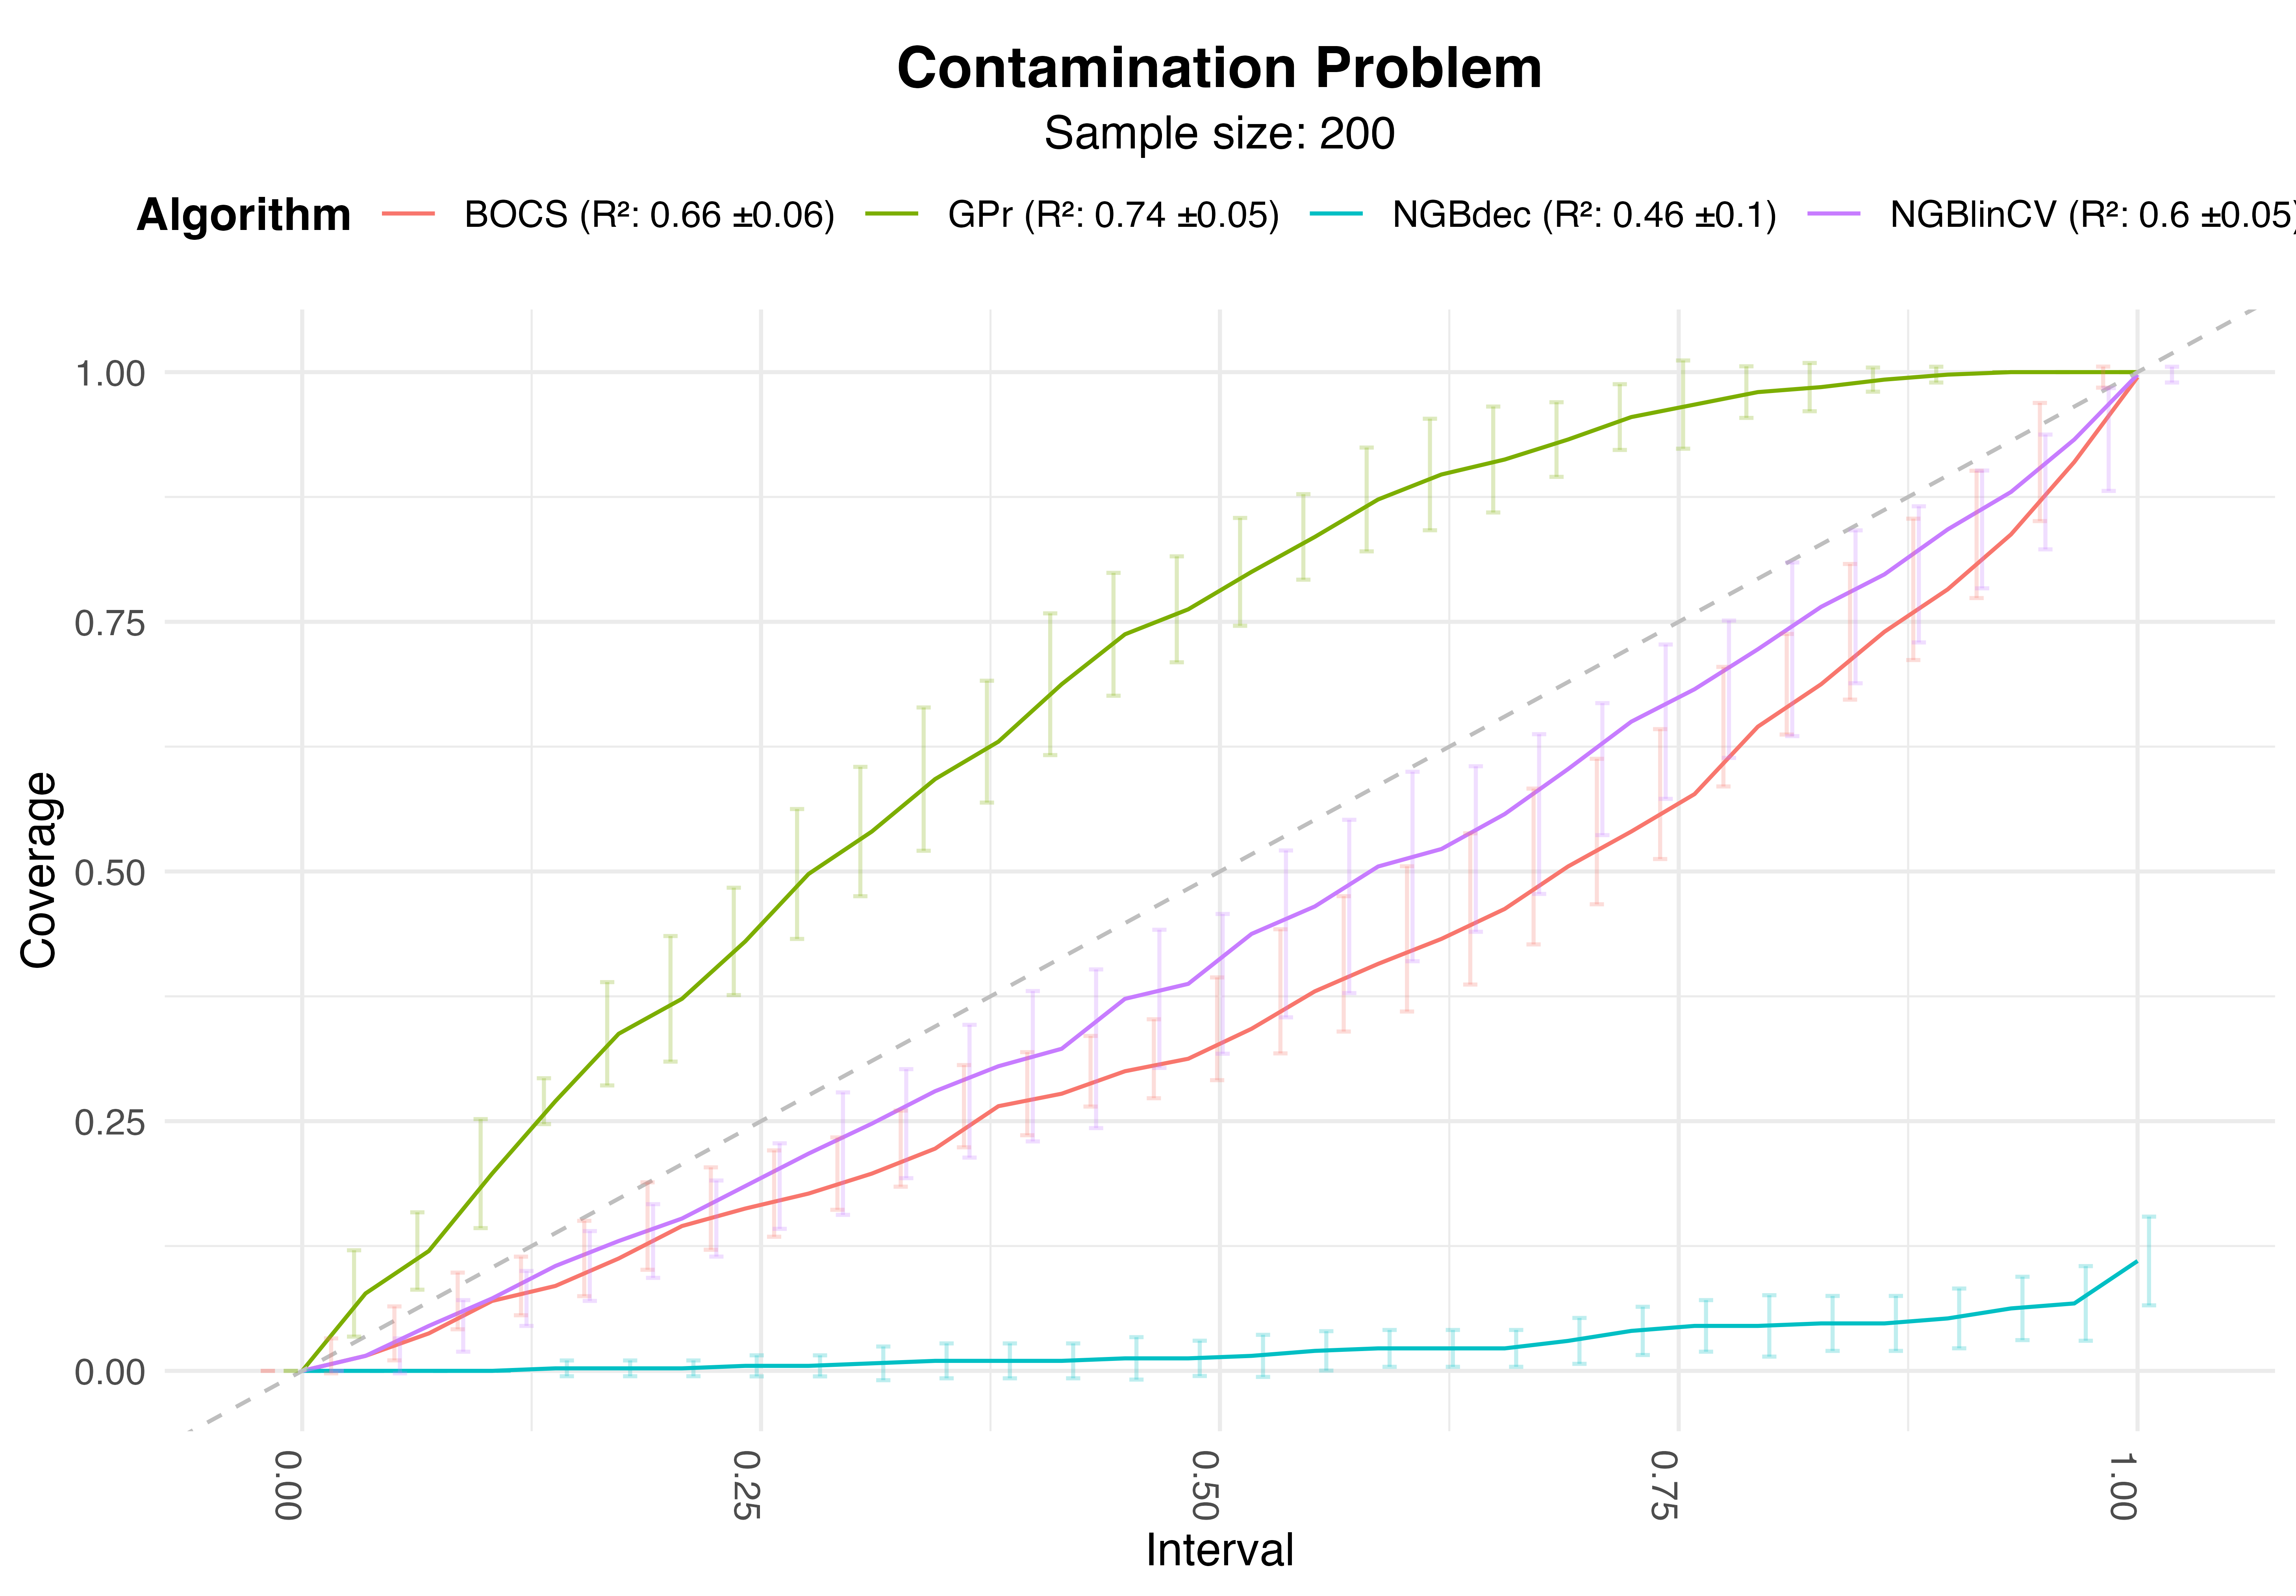
Calibrartion Plot and Performance Metrics. Sample size: 200
Results - Why?
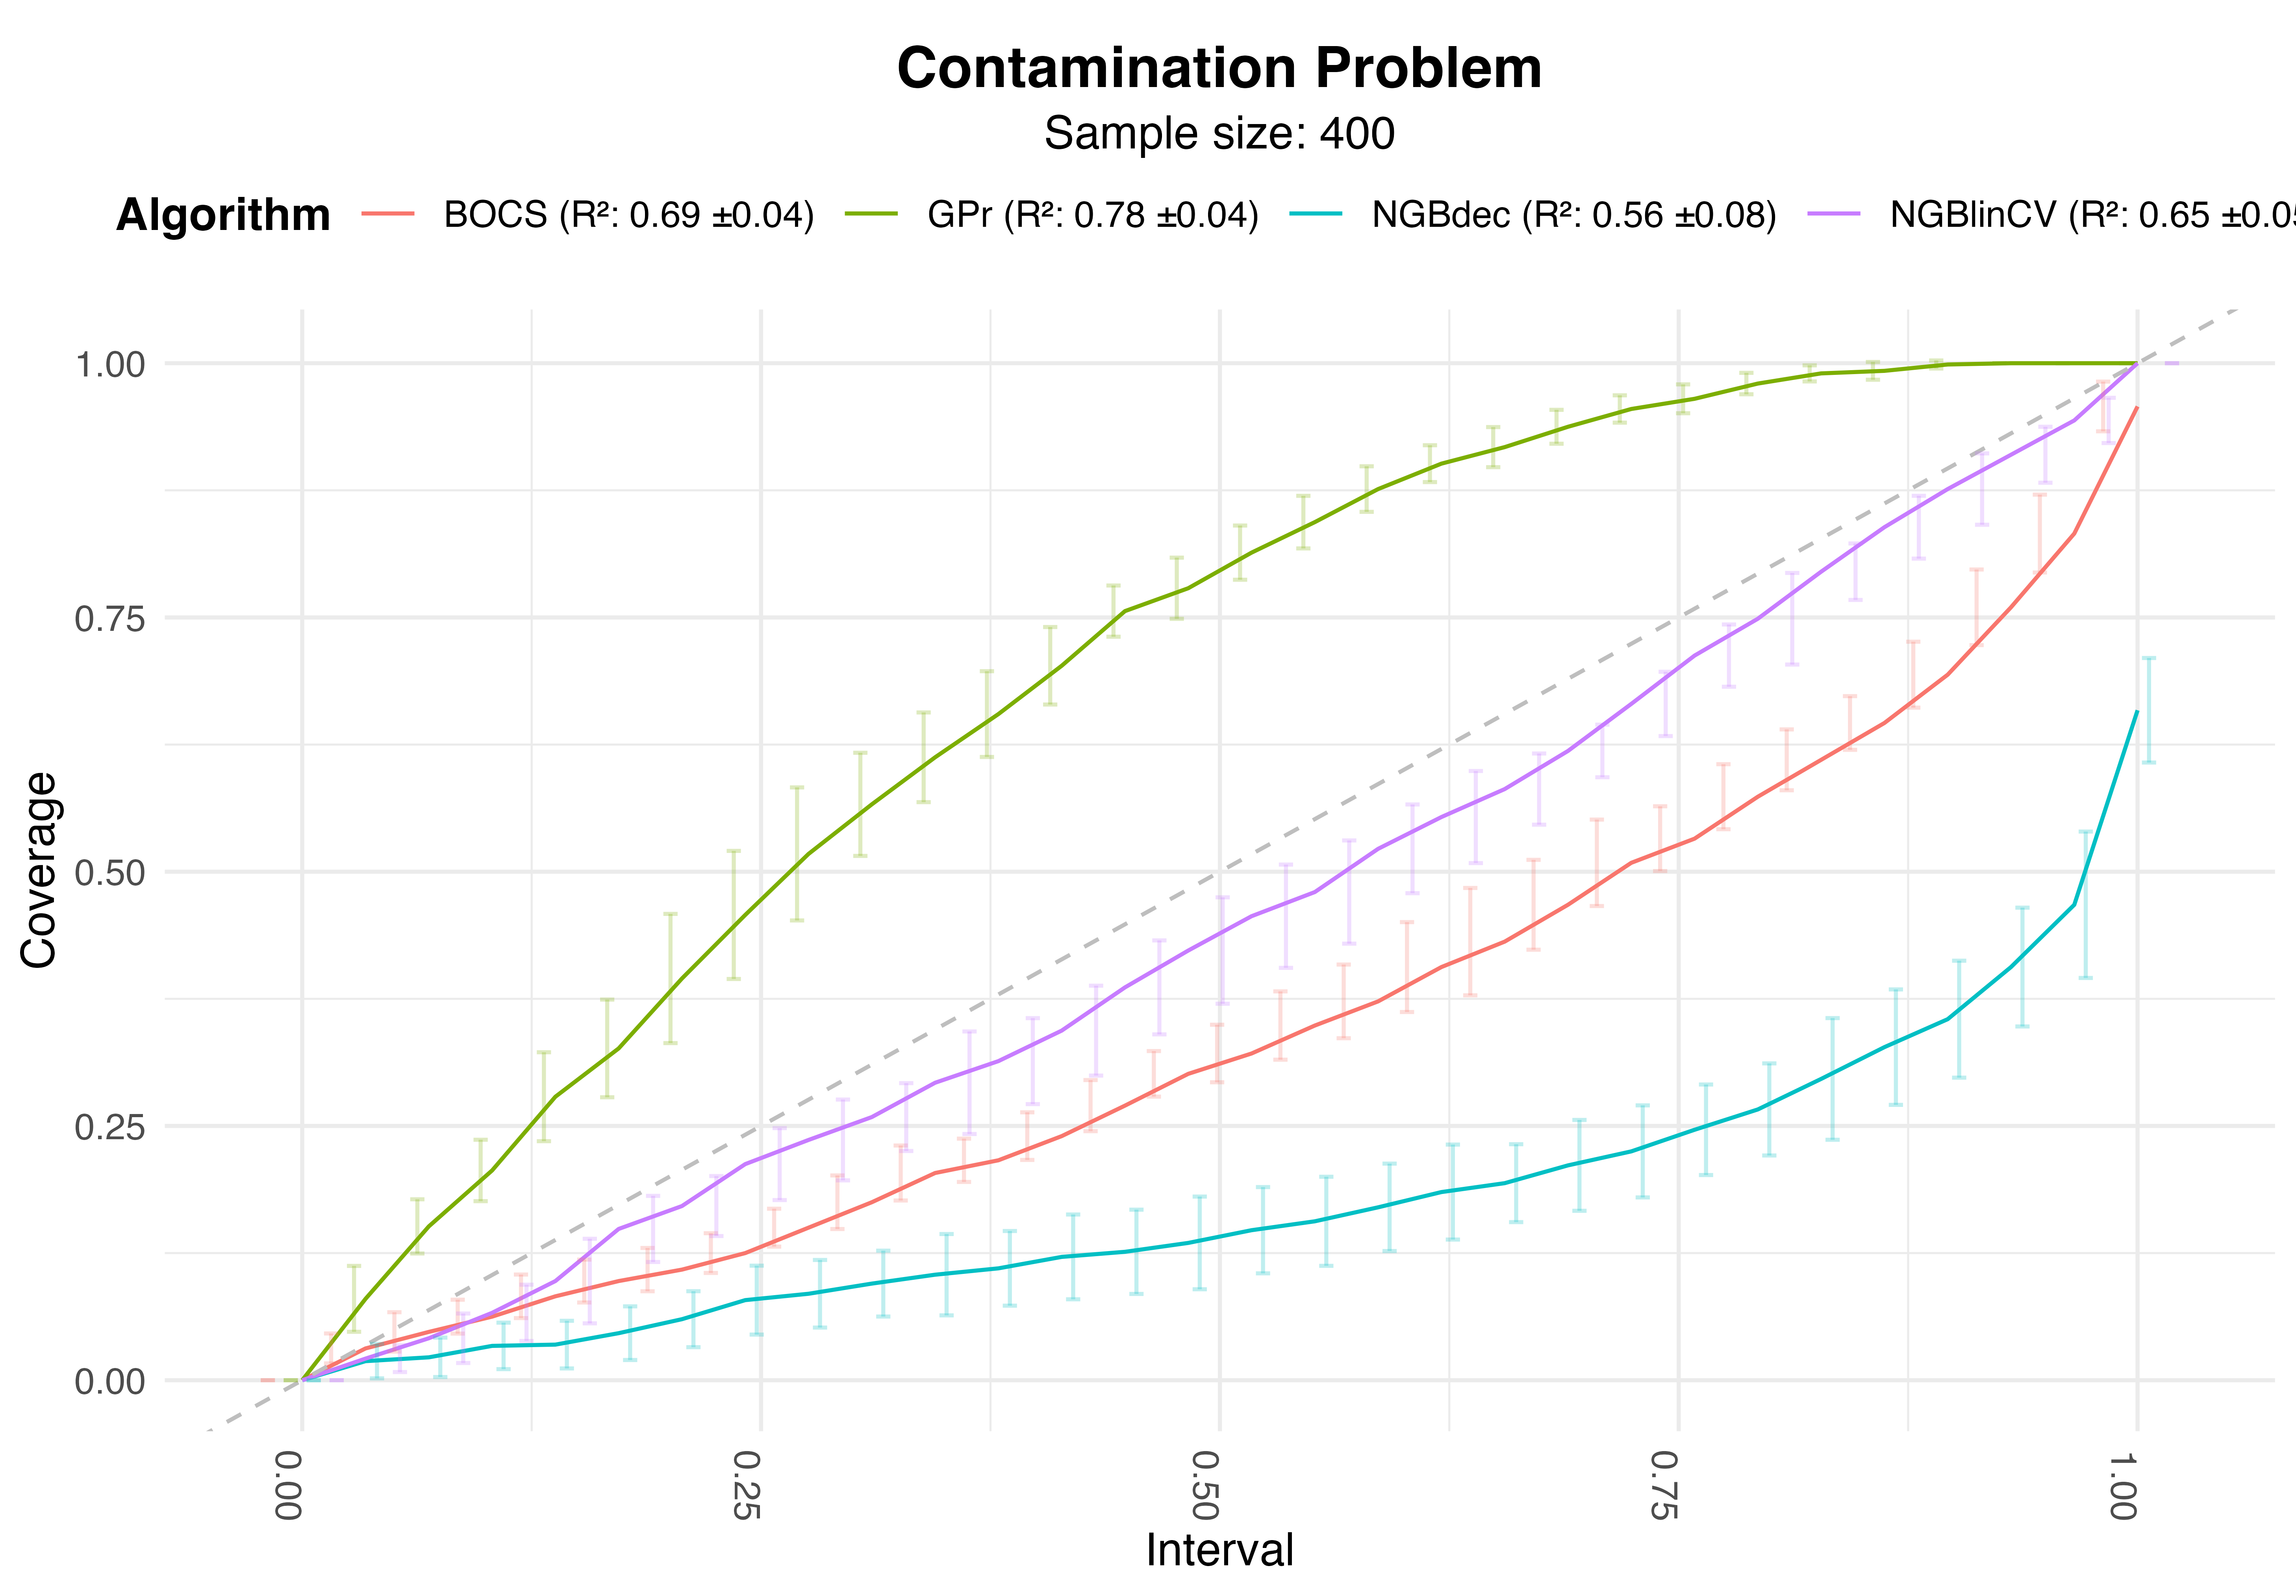
Calibrartion Plot and Performance Metrics. Sample size: 400
Conclusions
SBBO allows to do BO with any surrogate model (as long as we can sample from its PPD)
SBBO can be used to optimize expected utilities in combinatorial, continuous and mixed search spaces.
Future Work
More models: Bayesian non-parametric models such as BART
More problems…
Multiple proposals?
Multi-objective
Thanks!
Code available at my github!